Recursive Self Generation Exposes AI Memorization
The Privacy Problem Nobody Solved
Somewhere in the training data of every large generative model sits a photograph, a paragraph, a face that was never meant to be retained. The model was supposed to learn patterns, not memorize instances. But it did memorize, and the consequences have been quietly accumulating: personal images resurfacing in outputs, proprietary text bleeding through generations, medical records that should have been anonymized appearing verbatim in responses to unrelated prompts.
This is not a hypothetical. It is a documented property of how these systems work. Training data gets compressed into billions of weights, and some of it — the parts the model saw often enough, or the parts distinctive enough to leave a mark — stays retrievable. The privacy risk is severe and well understood. What has been missing is a practical way to detect it at scale.
The standard approach to finding out whether a specific piece of data was used in training has been to ask the model a single question and read the answer. Feed it a prompt, see if the output looks suspiciously familiar. This is the logic behind membership inference attacks, which try to determine whether a given sample was part of the training set. The problem is that one answer does not carry much signal. A model’s response to a single query is noisy, context-dependent, and often indistinguishable from what it would produce for data it has never seen.
Recent evaluations have shown how badly these single-query methods can fail. Under distribution shift — when the test data does not match the training conditions — many attacks barely beat random chance. The signal is there, but it is buried under too much noise to be useful.
What Recursion Reveals
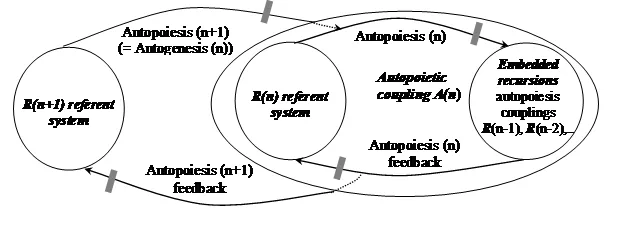
A different approach, described in the arXiv paper “Anchored or Drifting: What Recursive Self-Generation Reveals About Training Data” by Wojciech Łapacz and Stanisław Pawlak (2026), asks the model to keep talking to itself. Instead of one query, the auditor runs a recursive loop: the model generates from a sample, then generates from that generation, then from the next, and so on. At each step, the model has nothing to condition on but its own previous output. No external reference corrects the trajectory. Whatever happens is driven entirely by what the weights already encode.
The researchers describe this as recursive self-generation, and what they found is that it exposes a difference that single queries cannot. Training samples and held-out samples follow visibly different paths. A sample the model was trained on stays close to where it started — the trajectory remains anchored. A sample the model has never seen drifts, losing the specifics of the original within a few iterations and settling toward something else entirely.
The asymmetry is not subtle. The paper reports that the gap is measurable within a few steps, and it holds across model types: image autoregressive models, diffusion models, and large language models, including both Transformer and state-space architectures. [1] The behavior is not an artifact of one modality or one architecture family. It appears to be a general property of how these systems retain information.
The process may be described as straightforward, even if the implications are not. When a model generates from its own output repeatedly, it is drawing entirely on its learned distribution. If the starting point was a memorized sample, the model’s internal representation of that sample pulls the trajectory back toward it. The model “knows” this data in a way that shapes its output even when the original input is no longer present. If the starting point was not memorized, there is nothing to pull it back. The trajectory wanders toward whatever the model has learned in general, losing the particular.
Measuring the Difference
To turn this observation into something usable, the researchers defined two numbers that summarize a trajectory. The first is the contraction rate, which describes how quickly the trajectory settles. The second is the drift floor, the point at which it stops moving. A sample that stays near its origin has a low drift floor — it is anchored. A sample that moves far away has a high one — it is drifting.
These are not arbitrary measurements. The paper describes the contraction rate as depending on the generation strength the auditor chooses and the local sharpness of the model’s memory at that point. [1] The relationship is mathematical, not heuristic. The trajectory is not merely a metaphor for what the model remembers; it is a direct readout of it.
The practical payoff comes when these trajectory features are fused into existing membership inference attacks. The researchers did not replace the attacks; they added the recursive signal to them. The gain shows up most clearly at low false-positive rates, which is where privacy audits actually operate. At a 1% false-positive rate, the true-positive rate roughly doubled on the weakest baselines and still improved the strongest. [1] The gain held in 118 of 122 attack–model pairs, while AUC moved by about 5%.
This matters because false positives are expensive in privacy work. Accusing a model of memorizing data it did not memorize has real costs, both reputational and legal. An audit method that only works at high false-positive rates is not usable in practice. The recursive approach improves the signal exactly where it needs to be improved.
Not Just More Compute
A reasonable objection is that running a model recursively for several steps is just spending more compute, and that any method given more compute would do better. The researchers tested this directly. They spent equivalent compute on independent perturbations of the sample — feeding the model slightly different versions of the same input and averaging the results. This is the approach used by prior work on membership inference attacks. The recursive trajectory outperformed it.
The difference is that independent queries sample the model’s behavior at different points, but each query is still isolated. The recursive loop is not isolated. Each step conditions on the previous one, and the trajectory accumulates evidence that no single query contains.
The distinction is between asking the same question many times and asking a question that changes based on the answer. The first approach averages out noise but does not deepen the signal. The second approach follows the signal wherever it leads.
The Pathology That Became a Tool
Recursive generation has a bad reputation in machine learning. When models are trained on their own outputs — a process called model autophagy — they degrade. Diversity collapses, tails of the distribution disappear, and the model converges toward a degenerate approximation of reality. This has been documented in work on model autophagy disorder, and it is a genuine concern for anyone building training pipelines that include synthetic data.
But that work concerns a sequence of models, each retrained on the previous one’s output. The research described here uses a single frozen model. No retraining happens. The recursion is applied only at inference time, and the model’s weights never change. What is a failure mode during training becomes a measurement instrument after it.
The same dynamics that cause collapse when you train on synthetic data reveal what a model has memorized when you only generate from it. The trajectory toward degeneration is the signal. A sample that resists that pull is a sample the model holds tightly. A sample that succumbs is one it never really knew.
What This Changes for Privacy Audits
The practical significance is that privacy auditing no longer requires shadow models. The standard approach to membership inference has been to train auxiliary copies of the target model, calibrate against them, and use the comparison to detect memorization. This is computationally infeasible for large architectures. Training a copy of a frontier model is not something an auditor can do.
The recursive method needs nothing beyond the model’s ability to generate. It works on any generative model, in any modality, without access to weights or training data. The auditor’s position — outside the model, with only its outputs to work with — is no longer a limitation. The trajectory is shaped entirely by what the weights encode, and that is exactly what the auditor wants to read.
No shadow models, no additional access, no special privileges. The improvement appears across model families and modalities, which suggests the underlying phenomenon is general rather than specific to one architecture or training regime.
The Gap Between Detection and Prevention
Knowing that a model memorized something does not undo the memorization. The recursive method is a detection tool, not a fix. It tells you which samples are anchored in the model’s weights, which is useful for auditing, for compliance, for understanding what happened during training. It does not remove the memorized data or prevent it from being generated in response to adversarial prompts.
The research also does not claim to solve the broader problem of training data contamination. It provides a better signal for detecting membership, which is one piece of the puzzle. Mitigation — actually removing memorized data or preventing it from being learned in the first place — is a separate problem, and the paper does not address it.
What the work does show is that the information was there all along. A single query does not exhaust what the weights hold. The model’s behavior over repeated self-generation carries evidence that isolated queries miss. The trajectory is a richer readout than any single answer, and the difference between anchored and drifting samples is measurable, consistent, and useful.
The detail that shows how far practice is from the promise: the method improves existing attacks rather than replacing them. It is a signal to be fused into what auditors already do, not a standalone solution. The strongest attacks improve the least, which suggests the recursive signal overlaps with what the best methods already capture. The weakest attacks improve the most, which is where the practical gain lies.
The recursive trajectory does not require new infrastructure, new access, or new models. It requires running the model you already have in a loop and reading what happens — a detection signal that fits into the audits already being run.